
When building a durable workflow engine on Postgres, one of the most common questions we get is “does Postgres scale?” Now, there has been no shortage of blog posts on the subject (including ours), and at this point it’s beating a dead horse to say that a single Postgres database can get you remarkably far, handling tens of thousands of operations per second.
But what if you want to go past that? What if you have a workload that requires more than one database can handle, perhaps hundreds of thousands or millions of operations per second? Can Postgres scale then? In this blog post, we’ll show how we scaled Postgres-backed workflows to >1M workflow/sec.
1M Workflows/Sec
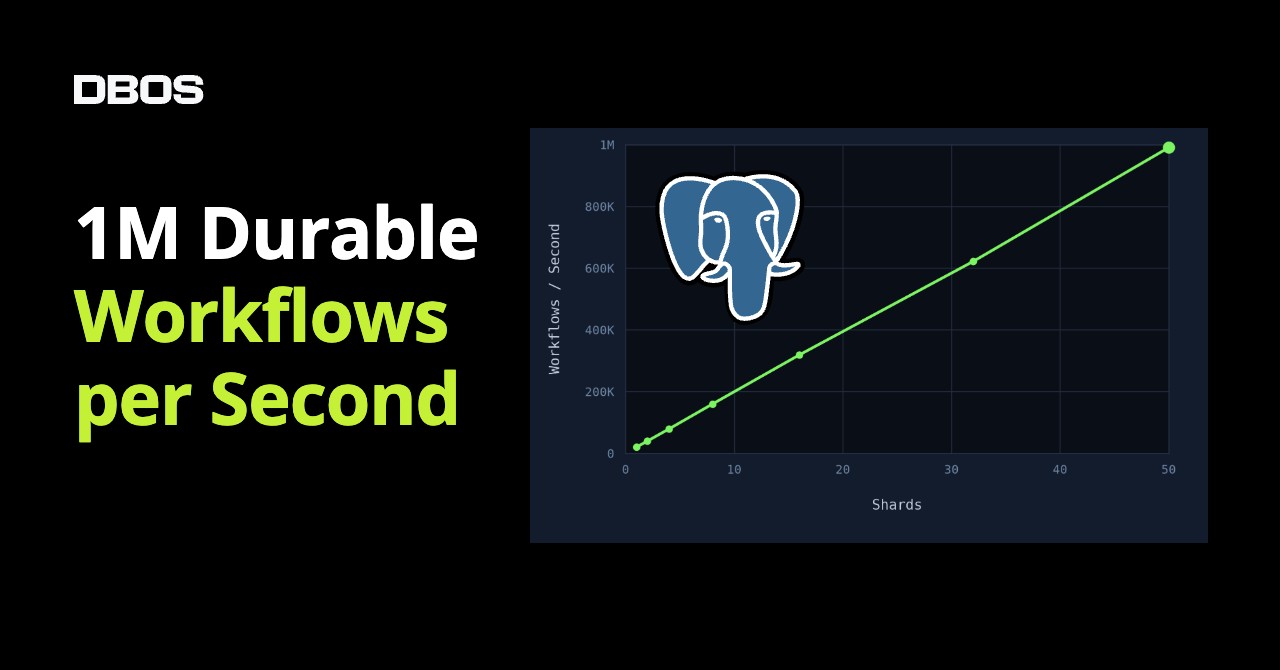
We’ll start with the good part: the results. By sharding durable workflows (using PgDog, but similar results are achievable with any sharding engine), we linearly scaled durable workflow throughput from 20K workflows/sec with one Postgres server to 1M workflows/sec with 50 Postgres servers:
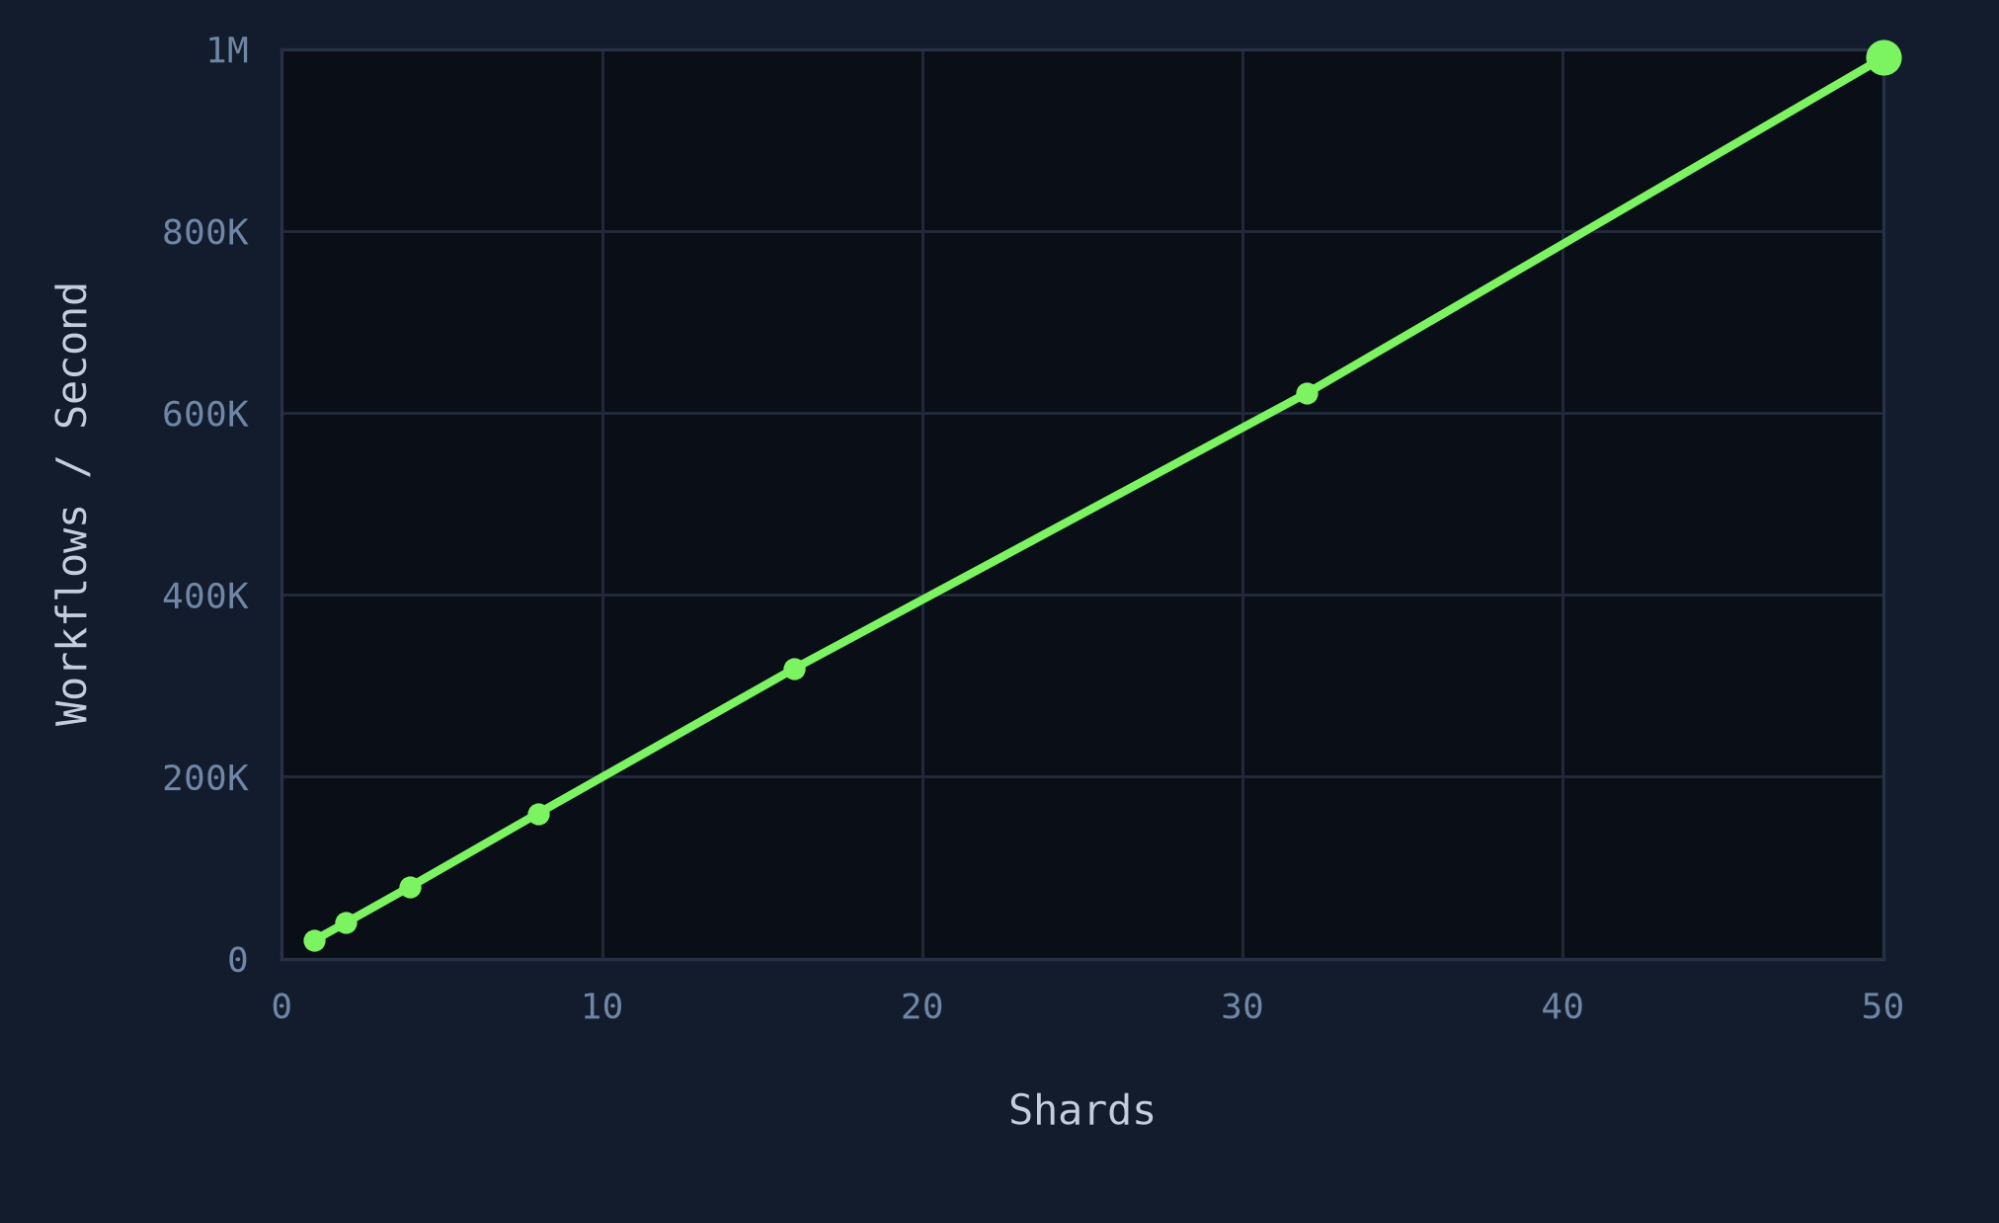
Here’s the benchmark design:
- We scale the number of shards from 1 to 50. Each shard is a db.m7i.4xlarge RDS Postgres with 16 cores and 64 GB of RAM.
- We scale worker processes across several client hosts. We launch 48 worker processes per shard, for a total of 2400 worker processes at 50 shards. All worker processes are identical. Each worker process connects to a PgDog router on its host.
- Worker processes enqueue 20K workflows/shard/sec, up to 1M workflows/sec at 50 shards. We chose this number because 20K workflows/sec is the maximum sustainable throughput of a single shard. The benchmark uses simple no-op workflows with no steps.
- Worker processes enqueue all workflows into a single durable queue. Each workflow has a uniformly random shard key, so workflows are evenly distributed across shards. All worker processes dequeue and execute workflows from this single queue.
- All benchmark code is open-source on GitHub.
How Sharding Works
Because Postgres is a single-node database, the only way to scale to >1M workflows/sec (well beyond the capacity of a single server, however large), is to shard it. Sharding is a technique for horizontally scaling a single-node database by distributing work across many database servers, called “shards”. There are many popular sharding engines: we used PgDog because it’s lightweight and open-source; other Postgres engines include Citus, Neki, and Multigres, and maybe the most popular sharding engine overall is Vitess for MySQL.
Sharding engines are powerful because they distribute work across many servers but present users with the abstraction that they’re working with a single database. To make this work, users select a “shard key” column for each of their tables. The sharding engine partitions each table by its shard key, creating an instance of each table on each shard and assigning data items to shards based on their shard keys. Data items with the same shard keys are always assigned to the same shard, while data items with different shard keys could be stored on different shards. At a high level, sharding looks like this:
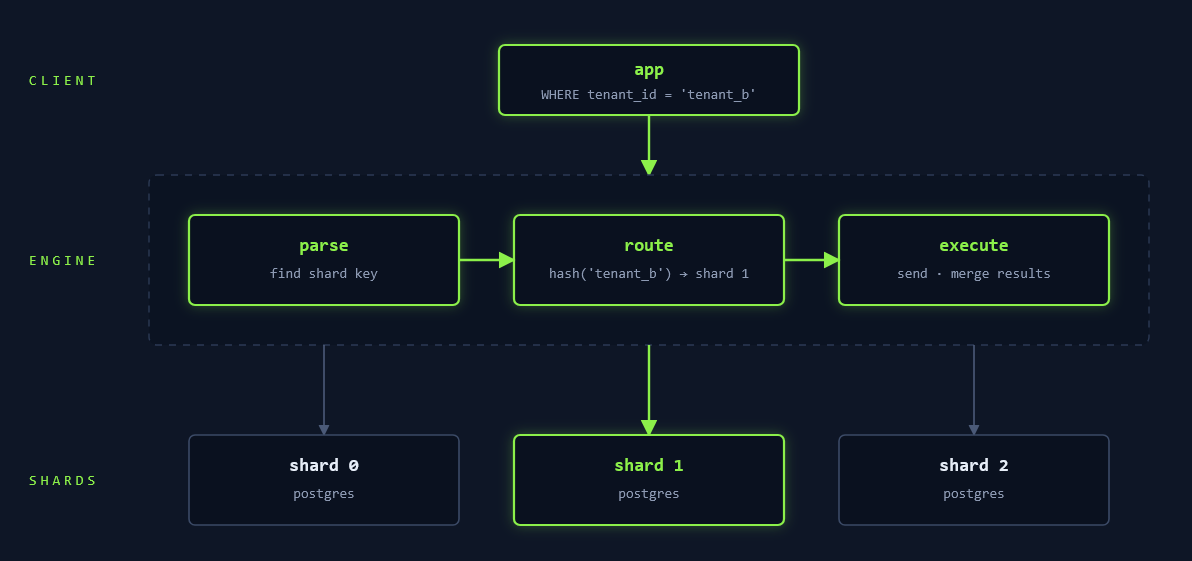
The core of a sharding engine is a router that parses queries and distributes them across the appropriate shards. If the query only needs data from a single shard (for example a SELECT query that specifies a single shard key value), that’s easy: the engine routes the query to that single shard and serves its response. If the query needs data from many shards (for example, an aggregation that does not specify a shard key), that’s harder: the engine must construct a distributed query plan that retrieves data from all those shards then combines their responses.
To make the performance of a sharded workload scale linearly, we must ensure each query can be served by a single
shard. Otherwise, coordination between shards limits performance. Thus, to shard workflows, we add a
shard_key column both to the main workflow_status table and to all dependent tables (such as
the workflow_steps describing each workflows’ steps). This way, all information about a single workflow
is stored on a single shard, and all operations done on a single workflow (such as enqueueing it, recording a step
checkpoint, or sending a message to it) can be served by a single shard. Similarly, we dequeue workflows by shard:
instead of dequeuing workflows from all shards at once, each process iterates through all shards, dequeueing workflows
from one shard at a time.
Metastability and Feedback Loops
When we initially tested sharded workflows, we found that past a certain point (roughly 8-16 shards, or ~200K workflows/sec), performance was metastable: it would initially appear to scale linearly, but if any shard was perturbed in any way (for example, a large VACUUM briefly slowed down the shard), cluster-wide performance would collapse and never recover.
The reason for this metastability was a negative feedback loop in dequeueing workflows. The query for finding
workflows to dequeue looks like the SQL below. Each process periodically polls each queue and shard, finding a number
(determined by flow control) of eligible enqueued workflows on that queue and shard and dequeuing them. To minimize
contention between workers, the query uses a locking clause (FOR UPDATE SKIP LOCKED), locking the
workflows it selects and selecting the first unlocked workflows in the queue.
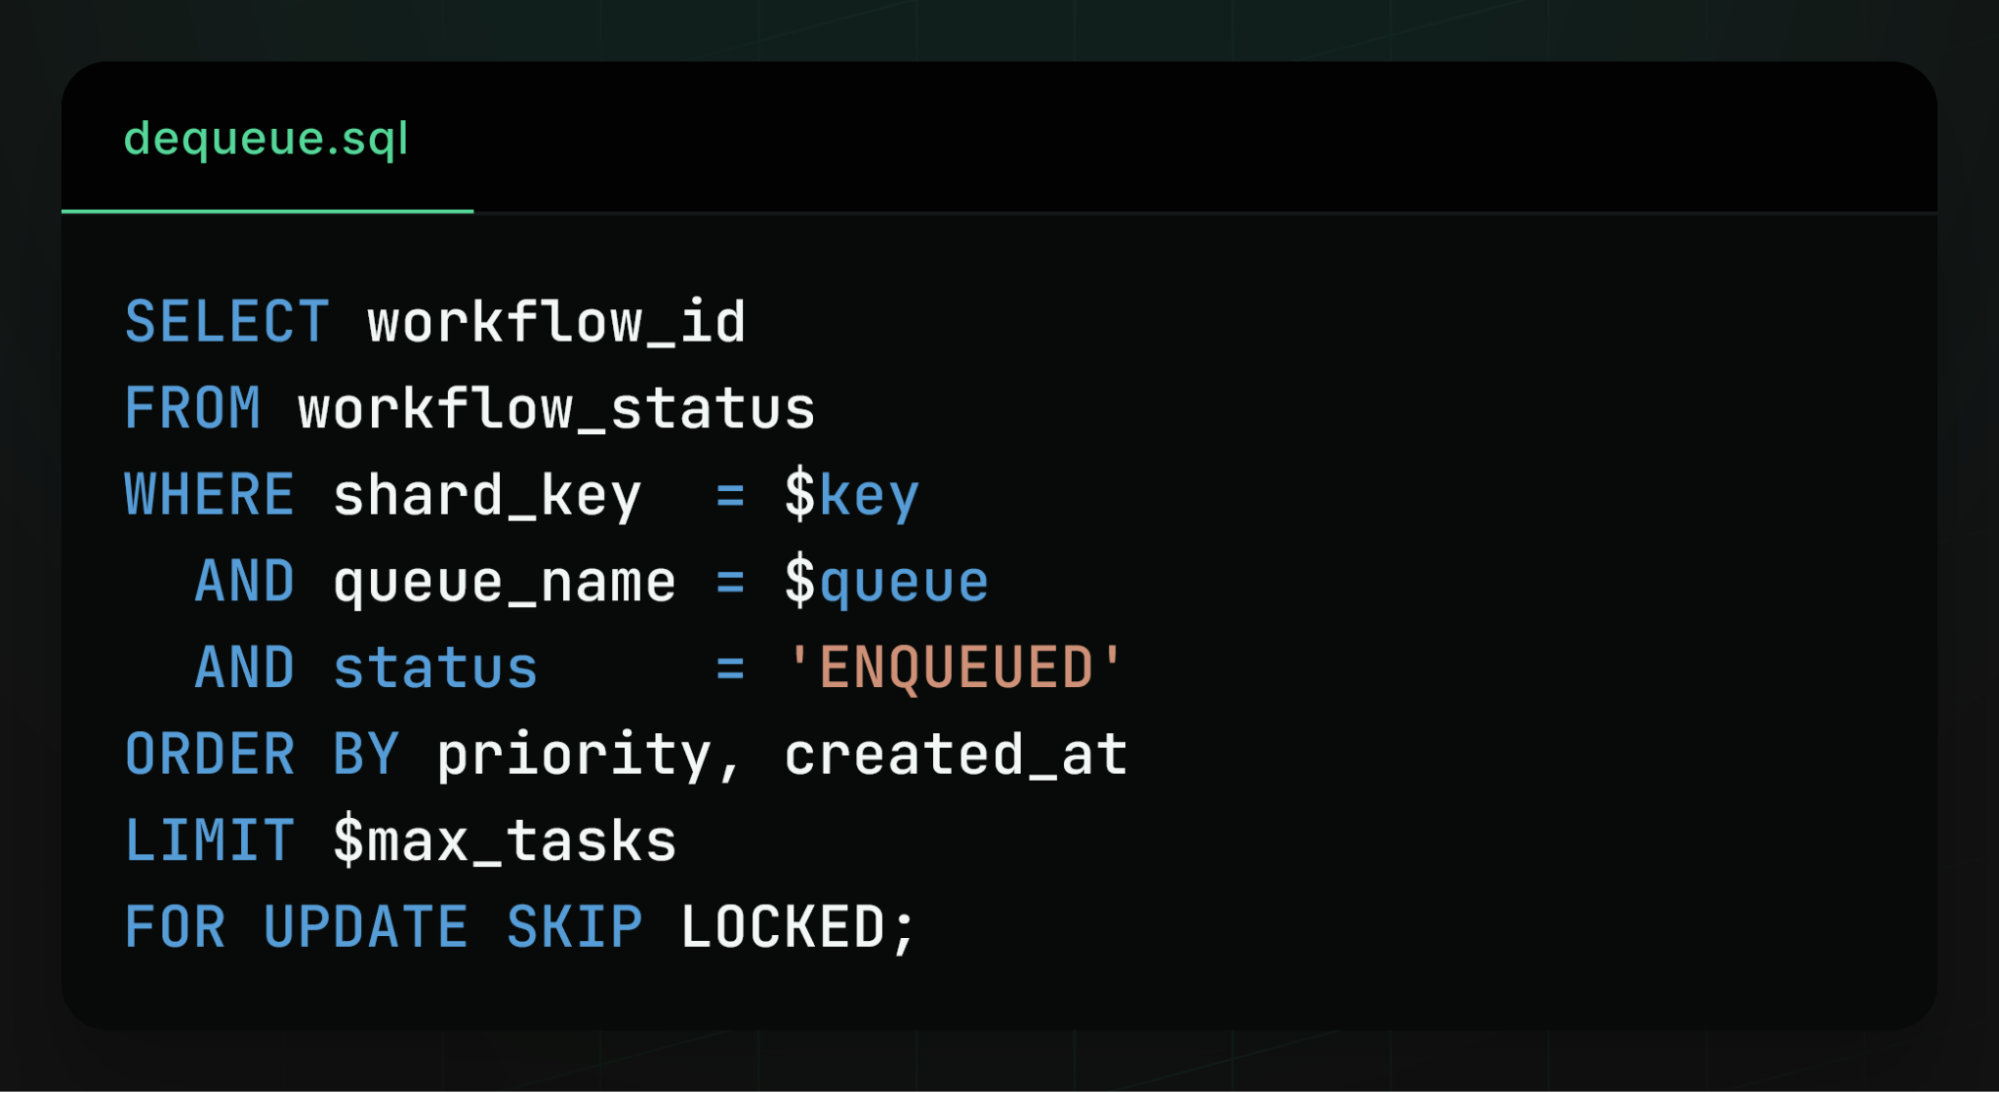
The issue with this query is that it is susceptible to a negative feedback loop at a high process count. Let’s say some event (such as a large VACUUM) causes a shard to momentarily slow down, so that each dequeue query takes longer. Because each dequeue query takes longer, more processes concurrently attempt to dequeue from that shard. The problem is that if more processes try to dequeue from a shard, queries on that shard take even longer (due to lock contention, earlier queries hold locks so newer queries have to search ahead to find unlocked workflows). This loop feeds back on itself until millions of rows are locked by queries taking several seconds each, collapsing performance.
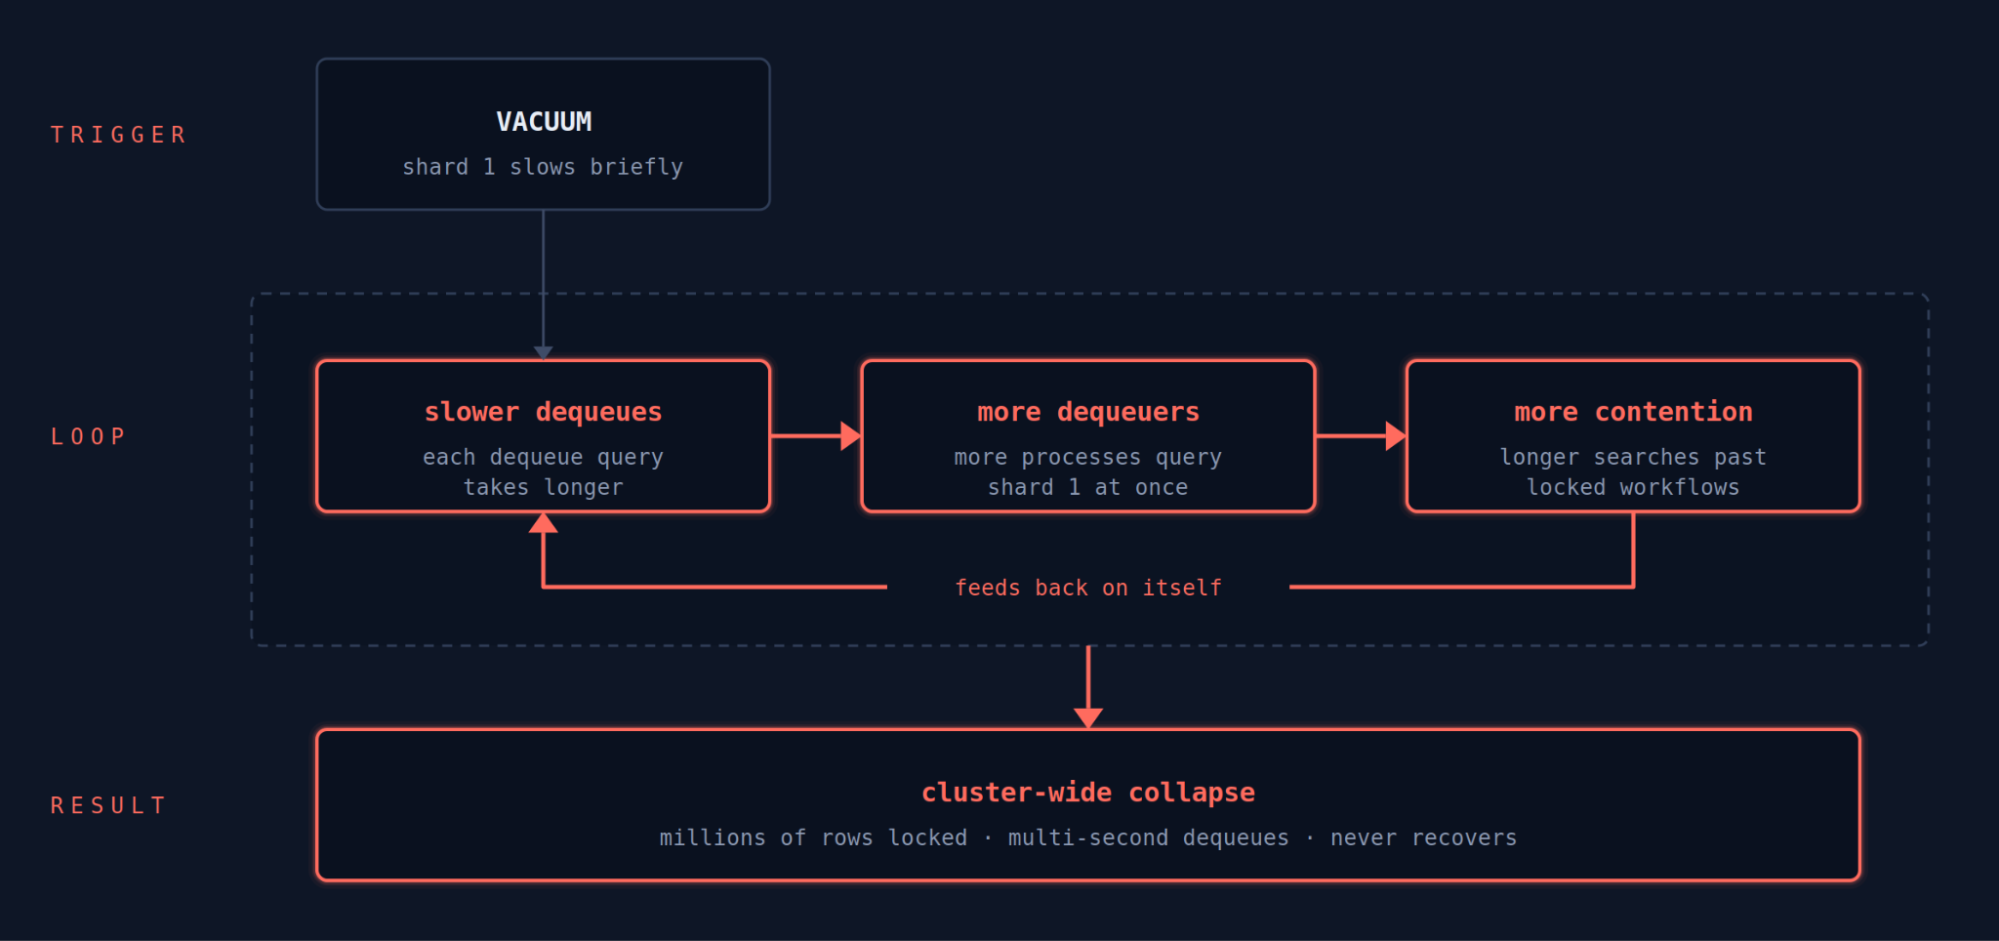
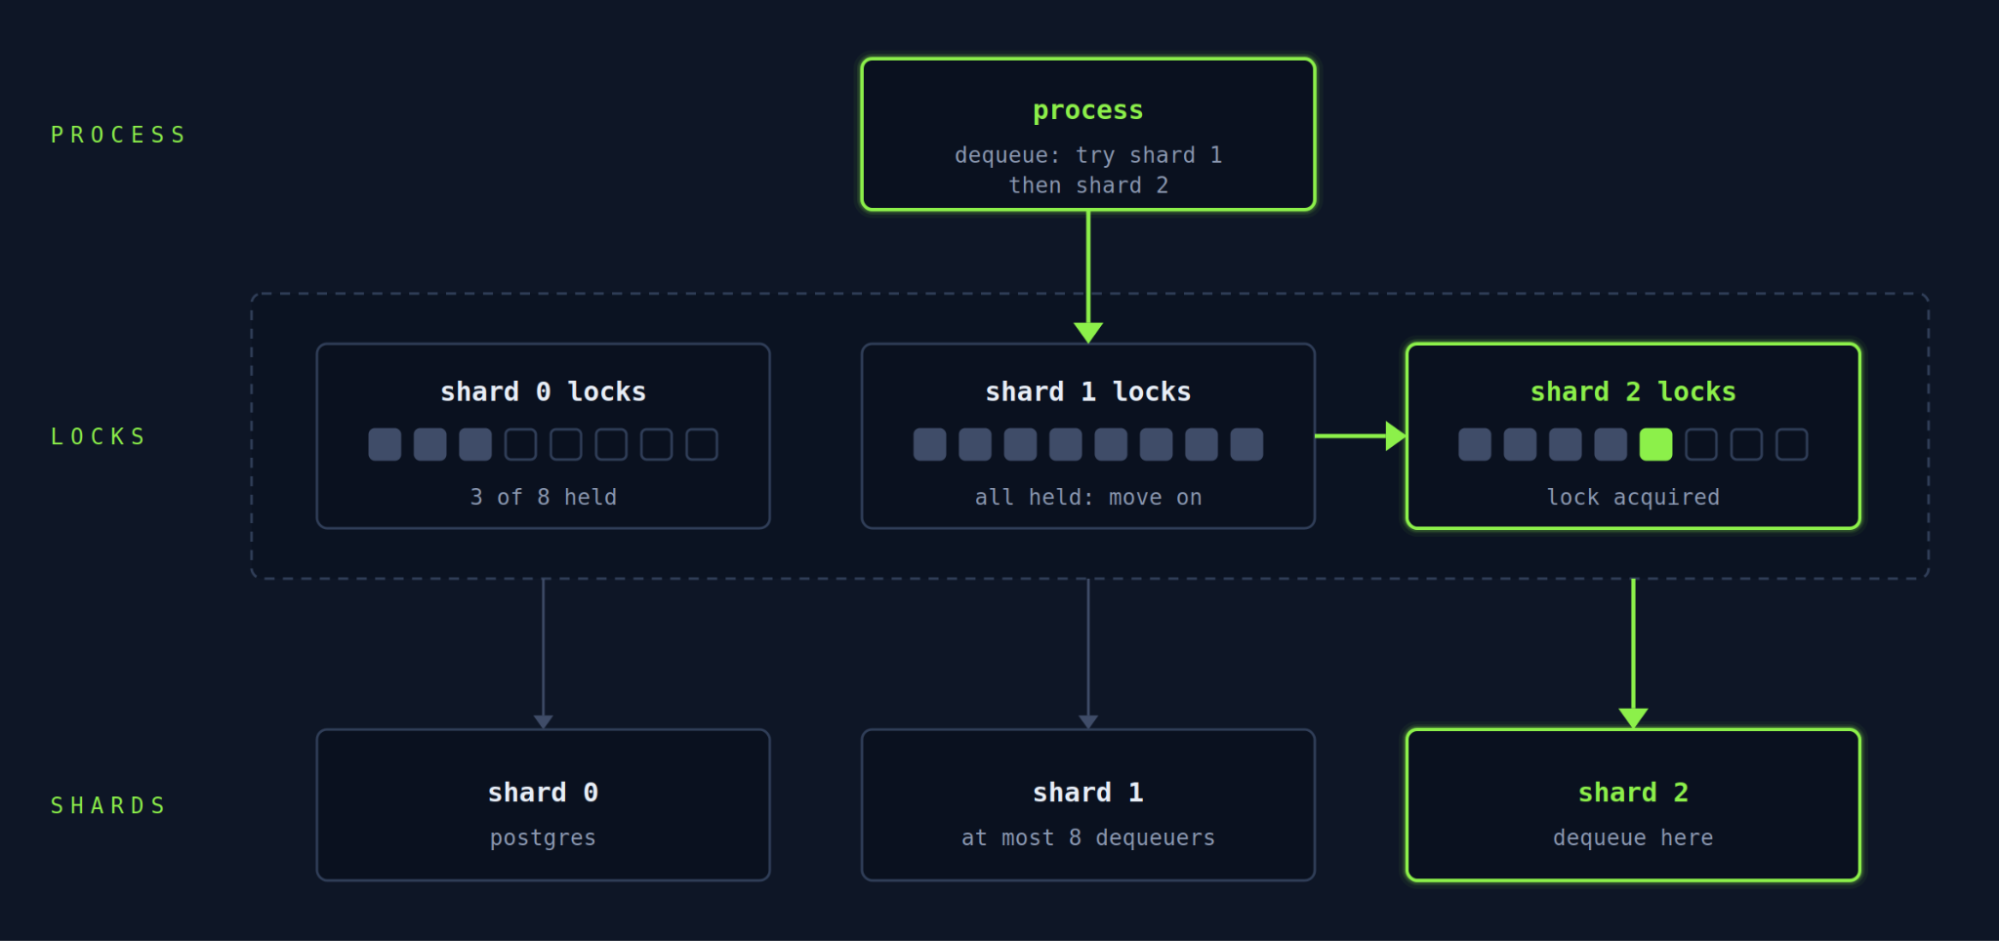
To fix this issue (and others like it), we had to stop the negative feedback loop by limiting concurrent accesses to a single shard. We did this using Postgres advisory locks. Each shard has a small number of “dequeue locks”. To dequeue from the shard, a process has to obtain one of the locks. If it can’t obtain a lock, it doesn’t wait, but rather moves on to the next shard and tries to dequeue from it instead. This design prevents a single shard from being overwhelmed, breaking the feedback loop and allowing stable scaling to 1M workflows/sec.
Learn More
If you like building scalable, reliable systems, we’d love to hear from you. At DBOS, our goal is to make Postgres-backed durable execution as simple and performant as possible. Check it out:
- Quickstart: https://docs.dbos.dev/quickstart
- GitHub: https://github.com/dbos-inc
- Discord community: https://discord.gg/eMUHrvbu67